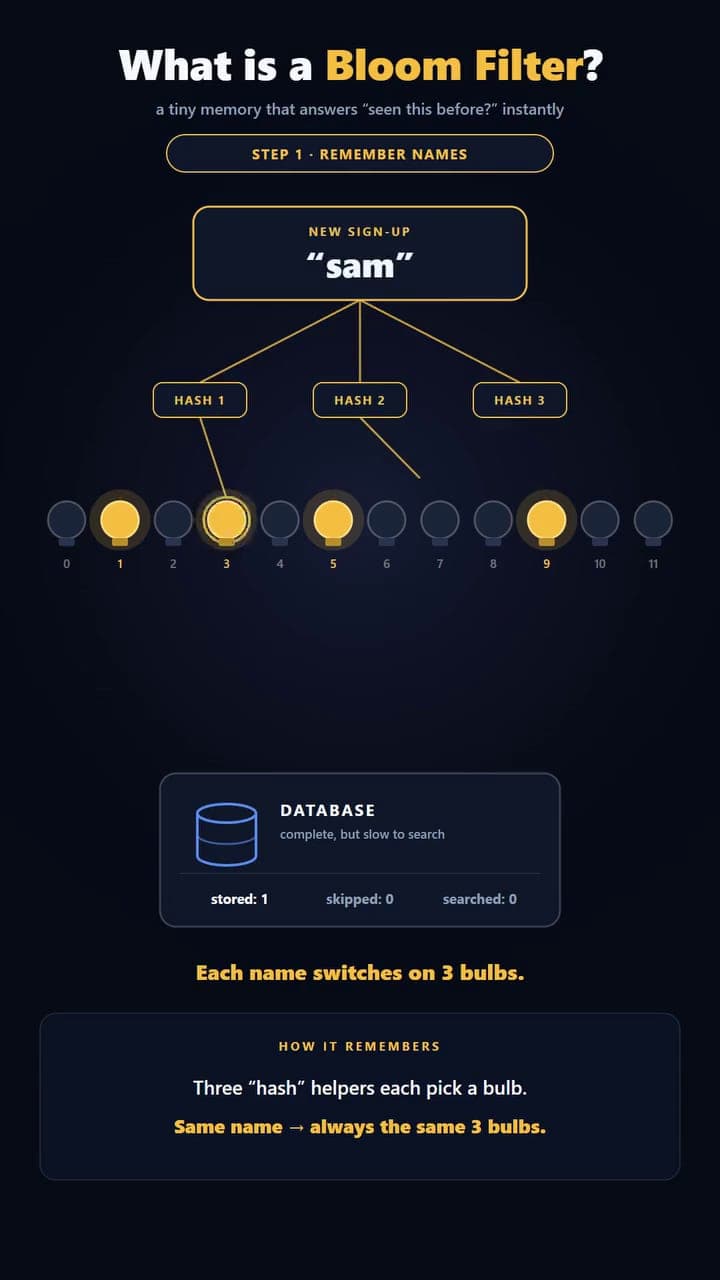
How Bloom filters skip wasted lookups
A Bloom filter is a tiny, fast data structure that answers "definitely not here" or "probably here" before you pay for a slow lookup.
Key takeaways
An item runs through several hash functions that switch on bits in a bit array.
If any of those bits is off, the item is definitely not in the set.
If every bit is on, the item is only probably there: false positives can happen.
Bloom filters never give false negatives and use very little memory.
Ever searched a database for something that was not even there? That wasted lookup still costs time: the database has to go looking before it can tell you the answer is no. A Bloom filter helps prevent exactly that. It is a tiny, super-fast data structure that answers with one of two replies: definitely not here, or probably here.
How it works
A Bloom filter is a row of bits, all starting switched off, plus a few hash functions. A hash function turns any input into a number, and the same input always produces the same number.
- Add an item. The item goes through multiple hash functions. Each result points at a position in the bit array, and those bits are switched on.
- Check an item. Later, the item you are looking for goes through the same hash functions, and the same positions are checked.
- Read the answer. If even one of those bits is off, the item definitely does not exist. If every bit is on, the item probably exists.
Picture a sign-up form that remembers usernames. Each new name switches on three bulbs in a row, and the same name always lights the same three.
Why "probably"?
Different items can sometimes switch on the same bits. Check a name that was never added, and every one of its positions might already be on because of other names. That is a false positive: the filter says "probably here" when the item is not. The reverse cannot happen. An item that was added always finds its bits on, so a Bloom filter never gives a false negative.
The rule is simple: probably yes, definitely no.
So a "probably" is not the final word. Only then does the system do the slow, exact check against the real data. A "no" skips that work entirely.
Why it matters
That trade makes Bloom filters useful wherever a lookup is expensive and many answers are no:
- Databases and caches
- Duplicate detection
- Web crawlers
- Distributed systems
Because they store bits rather than the items themselves, Bloom filters use very little memory, and they can save a system from doing thousands or millions of unnecessary database queries.